
Short answer: write en-GB with a hyphen. BCP 47 — the IETF standard that defines language tags, and the one HTML, HTTP and every browser API follow — separates subtags with a hyphen. The underscore in en_GB comes from POSIX and Java, which are older than the standard and never adopted it.
Both notations are alive and neither is going away, so the useful question is not “which is right” but “which does this file, API or framework expect”. This guide answers that, and shows how to move between the two without breaking your language files.
What a language tag is actually made of
A language tag is a sequence of subtags, most-general first:
language[-Script][-REGION][-variant]
| Subtag | Standard | Convention | Examples |
|---|---|---|---|
| Language | ISO 639-1, else 639-2/3 | lowercase | en, fr, zh, fil |
| Script | ISO 15924 | Titlecase, four letters | Latn, Cyrl, Arab, Hans |
| Region | ISO 3166-1 alpha-2, or UN M.49 | UPPERCASE | GB, CA, BR, 419 |
| Variant | IANA registry | lowercase | valencia, 1901 |
So sr-Latn-RS is Serbian, written in Latin script, as used in Serbia. es-419 is Spanish for Latin America, using a UN region code rather than a country. zh-Hans is Simplified Chinese with no region at all — which is usually what you want, since the script matters more than the country.
The relevant part of RFC 3066, the predecessor to BCP 47, is explicit about the separator:
The syntax of this tag in ABNF RFC 2234 is:
Language-Tag = Primary-subtag *( "-" Subtag )The character “-” is HYPHEN-MINUS (ABNF: %x2D).
It is equally explicit that tags are case-insensitive, and that the capitalisation conventions above are recommendations, not rules — ISO 3166 recommends uppercase country codes, ISO 639 recommends lowercase language codes. Follow them anyway: plenty of software that reads your files is stricter than the specification it claims to implement.
So where did the underscore come from?
The underscore predates BCP 47 by more than a decade. POSIX locales are named language_TERRITORY.codeset — fr_CA.UTF-8 — and that naming was inherited wholesale by:
- GNU gettext, whose message catalogues live in
locale/fr_CA/LC_MESSAGES/messages.mo - Java, whose
Localeclass andResourceBundlelookups usemessages_fr_CA.properties - Ruby on Rails and Python, whose ecosystems borrowed the convention from both of the above
None of this is wrong, it is simply a different namespace. The underscore was never a tag separator; it was a filename separator that happened to contain a tag. The confusion starts when a locale code travels from a filename into an HTTP header, or out of a JSON API into an <html lang> attribute, without being converted.
Which format does each ecosystem expect?
| Where | Expected form | Example |
|---|---|---|
HTML lang attribute |
hyphen | <html lang="pt-BR"> |
HTTP Accept-Language / Content-Language |
hyphen | Accept-Language: fr-CA, fr;q=0.9 |
| URLs and URL path segments | hyphen | /fr-ca/pricing |
JavaScript Intl and toLocaleString |
hyphen | new Intl.NumberFormat('de-CH') |
| CLDR and ICU data lookups | either (ICU normalises _ to -) |
fr_CA and fr-CA both resolve |
| Unicode CLDR file names | underscore | fr_CA.xml |
Java Locale / ResourceBundle |
underscore | messages_fr_CA.properties |
| GNU gettext directories | underscore | locale/fr_CA/LC_MESSAGES/ |
Rails I18n locale files |
either, hyphen is idiomatic | config/locales/fr-CA.yml |
| Android resource directories | hyphen, with an r before the region |
res/values-fr-rCA/strings.xml |
iOS / macOS .lproj bundles |
hyphen (underscore still works) | fr-CA.lproj/Localizable.strings |
.NET CultureInfo |
hyphen | new CultureInfo("fr-CA") |
Django LANGUAGE_CODE |
hyphen, lowercase region | LANGUAGE_CODE = "fr-ca" |
| Django locale directories | underscore | locale/fr_CA/LC_MESSAGES/ |
Django is the instructive case: the setting uses a lowercase hyphenated tag and the directory uses an underscored one, in the same project, by design. That is not a bug in Django; it is the seam between the web-facing standard and the POSIX-facing filesystem, sitting where it usually sits.
Converting between the two
Because the separator carries no meaning, converting the tag itself is a character swap:
# tag → POSIX
"fr-CA".tr("-", "_")   # => "fr_CA"

# POSIX → tag
"fr_CA".tr("_", "-")   # => "fr-CA"
What you must not do is assume the rest of the naming convention converts with it. Three traps:
- Android’s region prefix.
fr-CAbecomes the directoryvalues-fr-rCA, notvalues-fr-CA. The lowercaseris a separator Android invented for its own resource qualifier syntax. - The codeset suffix. POSIX locale names can carry an encoding —
fr_CA.UTF-8orfr_CA@euro. Strip everything from the.or@before treating the value as a language tag. - Case-folding on the way in.
FR-cais a valid tag but it will miss a case-sensitive hash lookup or a case-sensitive filesystem. Normalise to the conventional casing at the boundary, once, rather than defensively at each call site.
A safe normaliser does all three:
def normalize_tag(value)
  language, *subtags = value.to_s.split(/[.@]/).first.tr("_", "-").split("-")
  [language.downcase, *subtags.map { |subtag|
    case subtag.length
    when 4 then subtag.capitalize   # script:  Latn
    else        subtag.upcase       # region:  GB, 419
    end
  }].join("-")
end

normalize_tag("fr_ca.UTF-8")  # => "fr-CA"
normalize_tag("sr_latn_rs")   # => "sr-Latn-RS"
Five locale codes teams routinely get wrong
The separator is the question people ask. These are the ones that actually cost them a release.
zh-CN when they mean zh-Hans. Chinese splits by script, not country: Simplified versus Traditional. zh-CN says “Chinese as used in mainland China”, which implies Simplified but does not say it, and leaves Simplified-reading users in Singapore and Malaysia unmatched. zh-Hans and zh-Hant say what you mean. Use the region form only when something genuinely differs by country beyond the script.
pt-BR and pt-PT treated as interchangeable. They are not, and Brazilian Portuguese is the larger market by an order of magnitude. Shipping pt alone and hoping is a decision, not a default — decide which variant pt resolves to.
en-UK. There is no such region code. The ISO 3166 code for the United Kingdom is GB; UK is reserved and will not match. en-GB is the tag.
he versus iw, id versus in. ISO renamed Hebrew, Indonesian, Yiddish and Javanese decades ago, but Java froze the old codes for backwards compatibility and still returns iw from Locale("he").getLanguage(). Any code that compares locale strings across a JVM boundary needs to normalise these aliases explicitly.
Region codes used as language codes. de-AT is a language tag; AT on its own is a country, not a language. This surfaces in country-picker UIs wired straight into a locale lookup, and the symptom is a user in Austria getting English.
Why this matters more in a translation workflow than it looks
Inside your application the separator is cosmetic. Inside a translation workflow it decides whether two things are the same locale.
If your iOS project produces fr-CA.lproj, your Rails backend produces fr_CA.yml, and your web front end requests fr-ca, then a system that compares locale codes as plain strings sees three different languages. You get three sets of translations, three sets of translation memory, and translators doing the same work three times.
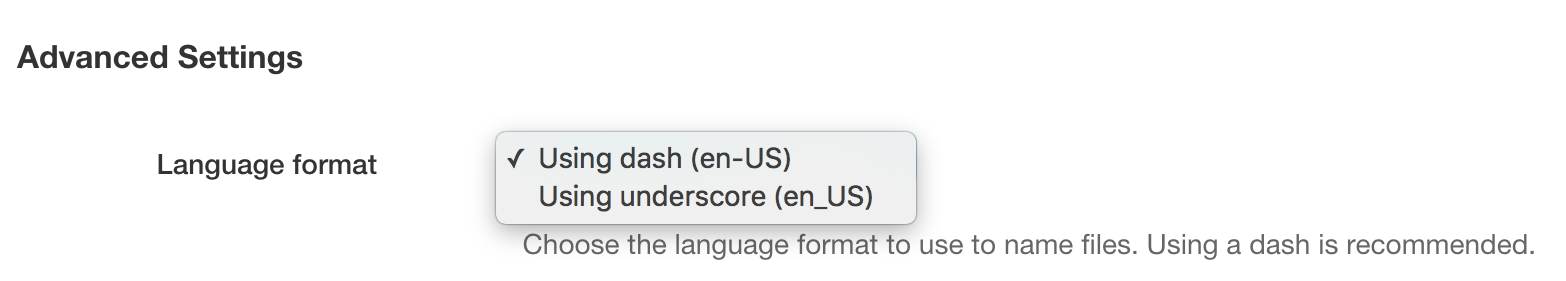
The fix is to normalise once, at the point where files enter the system, and to be deliberate about the form that comes back out. In WebTranslateIt that is a per-project setting: locales are stored canonically, and a single toggle decides whether generated file names, API URLs, and the language code written inside certain file formats use hyphens or underscores. Set it to match the toolchain that consumes the files, not the one that produces them.
A rule of thumb
- Store and compare locales in the hyphenated BCP 47 form. It is the standard, it is what the web platform speaks, and it is unambiguous.
- Convert to underscores at the filesystem boundary, for the specific tools that require it.
- Never let a raw, unnormalised locale string from user input, a filename, or a third-party API reach your lookup tables.
Get that right once and the en-GB versus en_GB question stops being a recurring bug and becomes what it should be: a formatting detail at the edge of your system.
Frequently asked questions
- Is en-GB or en_GB correct?
- en-GB is correct according to BCP 47, the IETF standard for language tags, which requires a hyphen between subtags. en_GB is a POSIX and Java convention that predates and sits outside that standard. Both are widely used; the hyphen is the one to write anywhere the value is web-facing, such as an HTML lang attribute, a URL, or an HTTP header.
- Does capitalisation matter in a locale code?
- BCP 47 declares language tags case-insensitive, so en-gb and EN-GB are technically the same tag. The conventions are still worth following: lowercase language (en), titlecase script (Latn), uppercase region (GB). Many parsers, file loaders and directory-based lookups are case-sensitive in practice even though the standard is not.
- Can I just replace underscores with hyphens everywhere?
- Not blindly. The separator character carries no meaning, so the conversion is lossless for the tag itself, but the name of the file, directory or resource key often is meaningful to the loader that reads it. Java expects fr_CA.properties, Android expects values-fr-rCA, and gettext expects fr_CA/LC_MESSAGES. Convert the tag, not the filename convention around it.
- What is the difference between a language code and a locale code?
- A language code identifies the language alone (fr). A locale code adds the region, script or variant subtags that change how the language is written or formatted (fr-CA, sr-Latn, es-419). A locale is what you actually ship, because number formats, date formats and vocabulary all vary by region.
Keep reading
-
Plural rules by language: the complete CLDR guide
A reference table of CLDR plural categories for 163 languages, plus why one does not mean 1 and how each i18n framework expects you to spell the rules.
-
Placeholder formats cheat sheet: %s, %@, %{name}, {{name}}, {0}
Every string placeholder syntax you will meet, which language or framework uses it, and what breaks when a translator retypes one by hand.
-
Locale codes, language tags & plural rules (documentation)
How WebTranslateIt builds locales, and the project setting that switches file names between hyphens and underscores.
Translate your app without the spreadsheet round-trip
WebTranslateIt reads the file formats and placeholder syntax described on this page, validates them as translators work, and syncs the results straight back into your repository.